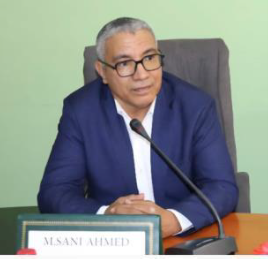
Dr. Ahmed Sani
Invited Speaker
Mathematics researcher and lecturer at the Faculty of Sciences of Agadir, Ibn Zohr University, since 2016, now serving as a Full Professor (Higher Education). Began his career teaching mathematics in secondary education and at the French school EFET, before joining the pedagogical inspectorate. Holds a PhD in Mathematics and has, since 2020, been accredited to supervise fundamental research in mathematics (functional analysis, evolution equations, copula theory). Was entrusted by colleagues with heading the Department of Mathematics. Author of around fifty publications, conference contributions and scientific reports spanning pure mathematics, applied statistics and mathematics education.
Rethinking Assessment in Higher-Education Mathematics in the Age of AI: Copulas as a Diagnostic Tool for Docimological Adequacy Abstract: The rapid diffusion of generative artificial intelligence has destabilised long-standing assumptions underlying assessment in higher-education mathematics. Traditional closed-book, procedure-heavy examinations, once reliable proxies for individual mastery, are increasingly vulnerable to AI-assisted completion, prompting institutions to redesign tasks toward authentic, process-oriented, multi-criteria evaluation. Yet redesigning an exam does not guarantee it still measures what it claims to: a persistent docimological question – is this instrument still adequate to its stated learning outcomes? – becomes more acute once items are reweighted, rubrics multiplied, or AI-resistant formats introduced. This work argues that copula theory, beyond its classical role in modelling stochastic dependence, offers a principled diagnostic for this adequacy problem. Rather than assuming independence between item scores, rubric dimensions, or human/AI-assisted performance channels, we estimate the empirical copula linking these components and compare it against the dependence structure implied by the intended assessment design (compensatory vs. conjunctive grading, or convergence between AI-detectable and AI-resistant task clusters). Departures from the expected pattern – captured through Kendall’s τ , tail-dependence coefficients, or extremal-point analysis of the admissible copula class – signal a misalignment between an examination’s actual measurement behaviour and its declared assessment philosophy, including cases where AI assistance silently decouples procedural fluency from conceptual understanding. This reframes docimological validation as a geometric and functional-analytic problem, extending prior work on asymmetric and extremal copulas to educational measurement, and complementing existing AI-assessment frameworks that remain largely qualitative. We outline a pilot protocol for testing exam adequacy across cohorts exposed to different levels of AI availability, contributing aquantitative bridge between mathematical research on copulas and the institutional urgency of reforming assessment in the generative-AI era. Keywords: Higher-education assessment, mathematics education, generative AI, Copulas; docimology, Examination validity.